

Why One Model for Everything Doesn't Scale
When you first build with a language model, you pick one and send everything to it. That works in a prototype. In production, it gets expensive and slow, because most requests don't need the most capable model. Classifying a support ticket, extracting a date from an email, or reformatting a text is a different job from reasoning through a multi-step legal question, yet both would pay the same price and wait the same time.
Models also differ in more than size. They vary in price per token, response speed, context window, tool support, and strengths. Some are better at code, others at long documents or structured output. Choosing deliberately for each task is the idea behind routing. If you are new to the underlying technology, it helps to first understand what an LLM is.
What Is LLM Routing?
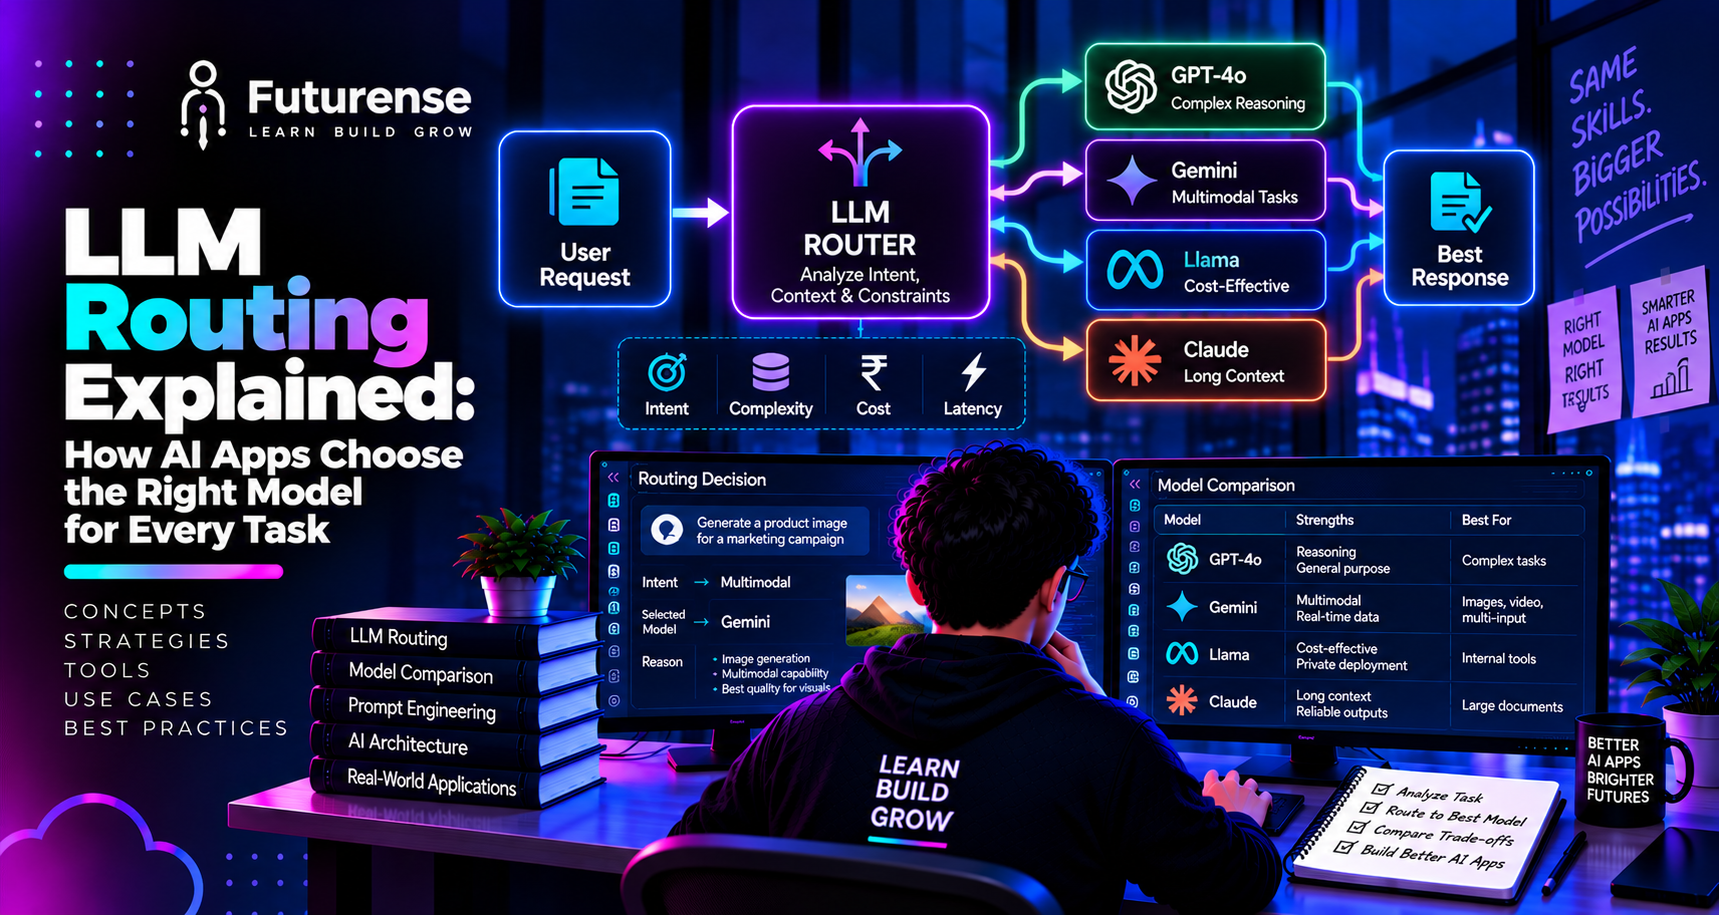
LLM routing is the process of automatically selecting which model, from a set of available models, should handle a given request, based on factors such as task difficulty, cost, latency, quality requirements, and policy constraints. The component that makes this decision is called a router.
A router sits between your application and the models. A request comes in, the router decides where it goes, and the response comes back. In many setups this lives in an LLM gateway, a layer that standardises access to different providers and already tracks cost and latency, which makes it a natural place to make routing decisions. The application still owns the definition of "good enough," because only it knows what quality means for each task.
Routing differs from two things it is often confused with:
- Load balancing spreads traffic across identical resources. Routing chooses between different models.
- Failover switches to a backup when a provider is down. Routing optimises cost, speed, and quality while everything is working. Logging them separately keeps your data clean.
The Main LLM Routing Strategies
Routing strategies form a ladder from simple to sophisticated. Most teams should start at the bottom and climb only when the data justifies it.
1. Rule-Based (Static) Routing
The simplest approach: route by an explicit label such as a task tag, endpoint, customer tier, or request header. "Summarisation goes to model A, code generation to model B." It is fast, predictable, and easy to debug. Its limit is that the caller must already know the task type.
2. Cost-Aware Routing
Pick the cheapest model that meets a quality bar defined for that task. The key is to measure total cost per request, not just the listed price per token, because different models can produce different numbers of output tokens for the same job and retries add up.
3. Latency-Aware Routing
Choose the fastest healthy model among those that meet quality requirements. This matters for interactive features such as chat and autocomplete, where response time shapes the user experience.
4. Semantic (Intent-Based) Routing
A lightweight classifier or embedding model reads the request, infers its intent or difficulty, and routes accordingly. It helps when requests arrive as free text and callers can't label them. It adds a small amount of overhead per request, and its categories can drift over time, so it needs a sensible default for ambiguous inputs.
5. Cascades
A cascade tries a cheaper model first and escalates to a stronger one only if a check fails. The check might be schema validation, a confidence signal, a rule, or a judge model. If the cheap model resolves most requests, the average cost falls sharply. The trade-off is latency: an escalated request pays for both calls.
6. Learned Routers
A learned router is trained on data about which model performs best on which kind of query. A well-known open-source example is RouteLLM, from the team behind LMSYS's Chatbot Arena. Secondary reports of its results say it reached about 95% of GPT-4's quality at roughly 26% of the cost on one benchmark, and that cost savings at that quality level varied widely by workload, from around 85% on conversational benchmarks to roughly 35% on math-heavy ones. Treat these as indicative: the figures are reported secondhand, depend on the model pair and benchmark, and your workload will differ.
A Worked Example: A Customer-Support Assistant
Imagine an assistant that handles three kinds of requests: tagging incoming tickets, answering policy questions, and drafting replies to complex complaints.
- Ticket tagging is a narrow classification task. A small, fast model handles it. This is the sort of job where small language models shine.
- Policy questions use retrieval and a mid-tier model, since the answer comes mostly from documents. The retrieval design is covered in RAG vs fine-tuning.
- Complex complaints go to a stronger model, or to a cheaper one first with a cascade that escalates if the draft fails a tone or policy check.
No single model is the right answer. The router matches the model to the job. With a cascade, if the cheap model resolves most requests and only a minority escalate, average cost can fall well below always using the frontier model. Whether that happens depends entirely on your traffic and quality bar, which is why you measure it rather than assume it.
How to Build an LLM Router, Step by Step
- Define the tasks. List the distinct request types your app handles.
- Set a quality bar per task. What does "good enough" mean? Build a small evaluation set of real examples with expected outcomes.
- Shortlist candidate models. Include at least one cheap and one strong option, and filter by hard constraints such as data residency, allowed providers, context length, and tool support.
- Measure each model on your tasks. Compare quality, latency, and total cost per request on your own evaluation set, not on public leaderboards alone.
- Start with simple rules. Route by task type. Only add semantic or learned routing if the measured savings justify the complexity.
- Add a cascade where it pays. Use a cheap model plus a reliable check, and define what triggers escalation.
- Log everything. Record which model handled each request, why, what it cost, and how long it took.
- Test changes before rollout. Use shadow traffic, canary releases, or A/B tests against business metrics.
- Review regularly. Models, prices, and your own traffic change, so routing decisions go stale.
This work usually falls under LLMOps, and understanding LLMOps vs MLOps clarifies how it differs from classical model operations.
What to Measure
A router that isn't monitored will drift. Track at least:
- Escalation rate for cascades, treated like a service-level objective.
- Blended cost per route and per task.
- Latency per route, including the routing decision itself.
- Quality per task, via offline evaluation sets, sampled reviews, a judge model, or A/B tests.
- Fallback and failure rates, kept separate from optimisation decisions.
These signals belong in your wider monitoring practice; see AI observability for what to watch in LLM and agentic systems.
Common Pitfalls
- Silent cascade drift. A provider update or a changed output format can make a validation check fail more often, escalating most traffic to the expensive model. Costs rise with no errors. Alert on escalation rate.
- Routing on gut feel. Without per-task evaluation, you can't tell whether a cheaper model is actually good enough. Every routing change should pass a measured quality gate.
- Judge models with blind spots. A judge that shares the generator's weaknesses may approve bad outputs. Sample and spot-check.
- Invisible counterfactuals. A router only sees the result of the model it chose. Use shadow evaluation or champion-challenger tests to learn what you're missing.
- Over-engineering early. A learned router needs labelled data, evaluation infrastructure, and retraining. Many teams get most of the benefit from simple rules and one cascade.
- Ignoring latency. Embedding-based routing and cascades add time. For interactive features, count it.
- Treating published savings as guarantees. Reported savings, including the benchmark numbers above, depend on the workload. Verify on yours.
Where Routing Fits in Agents and Multi-Model Systems
In agentic applications, routing multiplies. A planning step might use a strong model, tool-calling steps a mid-tier one, and summarisation a small one. Different roles in multi-agent systems often run on different models for exactly this reason. Routing is one decision inside the broader coordination layer described in AI orchestration, and its place in the stack is clearer once you see the overall AI agent architecture.
Building a Career Around Model Selection and Cost Control
As more companies ship LLM features, cost and reliability become engineering problems, not afterthoughts. Engineers who can evaluate models on real tasks, design routing and fallback logic, and monitor quality in production are in demand. Skills that matter include evaluation design, API and gateway integration, cost analysis, and observability. If you are mapping the path, start with how to become an AI engineer, and build a small project that routes between two models with a measured quality comparison. Showing the numbers behind your choice is what sets a portfolio apart
TL;DR: LLM routing is the policy an AI application uses to pick which language model handles each request. Instead of sending every query to one expensive frontier model, a router sends simple tasks to cheaper, faster models and reserves the strongest models for hard ones. Common strategies include rule-based routing, cost- and latency-aware routing, semantic (intent-based) routing, cascades that escalate when a cheap answer fails a check, and learned routers. Done well, routing cuts cost and latency without hurting quality. Done carelessly, it quietly degrades answers or inflates your bill. This guide covers how it works, which strategy to pick, and how to avoid the common traps.
What is LLM routing?
LLM routing is the process of automatically selecting which language model handles each request, based on factors such as task difficulty, cost, latency, quality needs, and policy constraints. The component that decides is called a router.
How does LLM routing reduce costs?
It sends simple requests to cheaper, faster models and reserves expensive models for tasks that need them. Strategies like cascades try a cheap model first and escalate only when a check fails, so the average cost per request falls if most requests resolve cheaply.
What is the difference between LLM routing and failover?
Routing chooses between models to optimise cost, speed, and quality while everything works. Failover switches to a backup when a model or provider is unavailable. They solve different problems and should be logged separately.
What is a cascade in LLM routing?
A cascade calls a cheaper model first and checks the result, using a schema check, confidence signal, rule, or judge model. If the check fails, the request escalates to a stronger model. It saves cost on easy requests but adds latency to escalated ones.
Do I need a learned router or are rules enough?
Many teams get most of the benefit from simple rule-based routing and one cascade. Learned routers can add further savings on large, varied traffic, but they need labelled data, evaluation infrastructure, and periodic retraining, so adopt them only when measurements justify the effort.
How do I know a cheaper model is good enough?
Build an evaluation set of real examples for each task, define a quality bar, and compare models on quality, latency, and total cost. Re-check after any model, price, or traffic change.


Advanced PG Certificate in AI Engineering on Cloud and AIOps
IIT Roorkee
Engineer AI Systems for Top Enterprises, with the Most Critical Skills of the Decade.