

What Does It Mean to Evaluate an LLM Application?
Evaluating an LLM application means measuring how well the complete system, including prompts, retrieval, tools and guardrails, does the job it was built for. It is different from evaluating a model.
- Model evaluation compares models on general benchmarks. It tells you which model is generally capable.
- Application evaluation tests your prompts, data and workflow on your tasks. It tells you whether your product works.
A strong model inside a poor prompt, with weak retrieval, still produces a poor product. If you are new to the underlying technology, begin with what an LLM is.
Why Ordinary Testing Is Not Enough
Traditional software tests check for exact outputs. LLM outputs vary in wording, may be correct in several different forms, and can fail in ways that read perfectly well. A response can be fluent, confident and wrong.
Three problems follow:
- Open-ended answers. There is rarely one correct string to compare against.
- Multiple dimensions of quality. Accuracy is not enough. Stanford's HELM project evaluated 30 prominent models across 42 scenarios, and measured seven kinds of metric: accuracy, calibration, robustness, fairness, bias, toxicity and efficiency. The lesson is that one number hides trade-offs.
- Changing behaviour. Prompt edits, model upgrades and new documents can change results without any code change.
NIST's Generative AI Profile adds a useful principle for risk: evaluations should be proportional to the identified risks. A homework helper and a loan assistant need different depth.
Step 1: Define What "Good" Means
Write down the job in plain language, then list the qualities that matter. For a support assistant, that might be:
- The answer is correct according to company policy.
- It cites or uses the right source.
- It refuses or escalates when unsure.
- The tone is polite and concise.
- It never reveals private data.
Turn each quality into something checkable, called a rubric. "Correct" becomes "states the right number of leave days." "Escalates" becomes "includes the phrase to contact HR when policy is missing." Vague goals produce vague scores.
Step 2: Build a Golden Dataset
A golden dataset is a set of realistic inputs paired with the expected behaviour. It is the foundation of every other step.
Where cases come from
- Real user questions or support tickets, with personal data removed.
- Questions from domain experts.
- Known failures and bug reports.
- Edge cases: missing information, ambiguous questions, other languages or mixed Hinglish, very long inputs.
- Adversarial inputs, including prompt injection attempts.
What to store for each case
- The input and any context.
- The expected answer or the facts it must contain.
- Things it must not say.
- A category tag, so you can see where it fails.
Start with 30 to 50 carefully chosen cases and grow from there. There is no magic number; it depends on how varied your traffic is and how costly mistakes are. Quality and coverage matter more than size. Keep a held-out slice that you never tune against, or you will quietly overfit your prompts to your tests.
Step 3: Choose Metrics That Match the Task
Pick metrics from the task, not from a tool's default list.
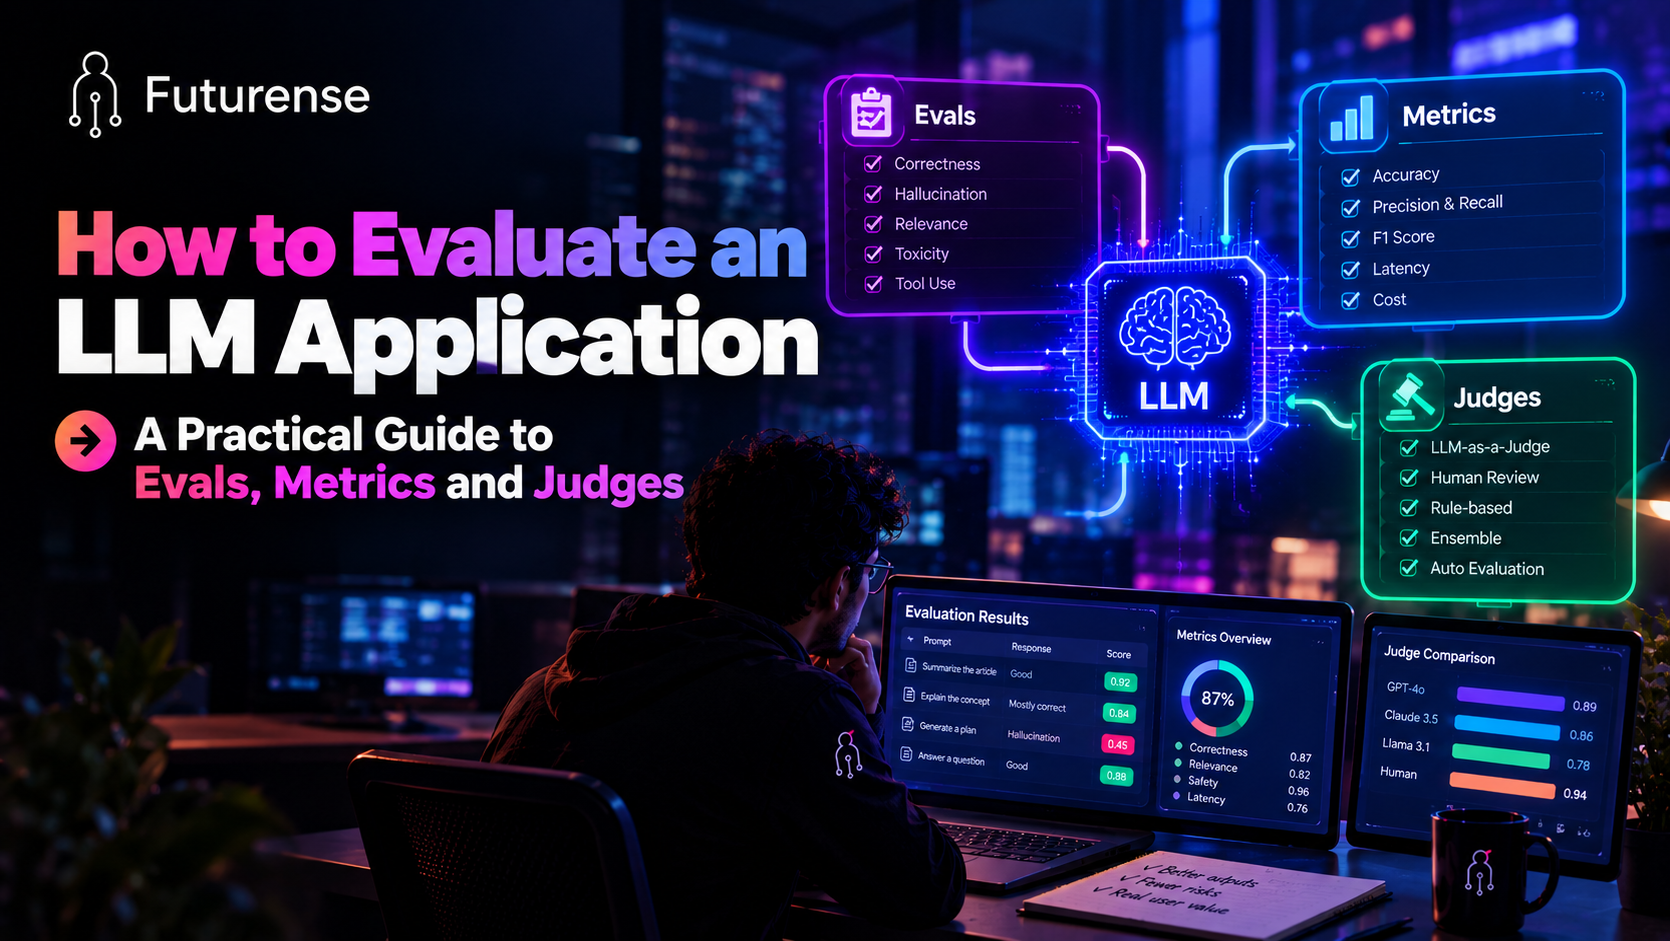
Where an answer can be checked by code, use code. Format validity, required keywords, JSON schema, numeric values and tool names are all cheap to test and fully repeatable. Use model-based or human grading only for what code cannot judge.
Step 4: Pick Your Graders
You have three kinds of grader, and most good setups use all three.
Code-based checks. Fast, free and deterministic. They cannot judge nuance.
Human review. The gold standard for subtle quality, and essential for building trust in your other graders. It is slow and expensive, so use it on samples and on disagreements.
LLM-as-a-judge. Using a strong language model to grade another model's output against a rubric. A 2023 NeurIPS paper by Zheng and colleagues found that GPT-4 as a judge reached over 80% agreement with human preferences, roughly the level at which humans agree with each other. That makes it a scalable approximation of human review.
The same paper documents limits you must plan for: position bias, verbosity bias, self-enhancement bias and limited reasoning ability. In practice:
- Give the judge a clear rubric and ask for a reason before the score.
- Randomise or swap the order when comparing two answers.
- Do not let a model grade its own family's outputs without checking.
- Calibrate against humans: have people grade a sample and compare.
- Prefer simple scales or pass/fail over fine-grained 1 to 10 scores.
How to Evaluate a RAG Application
Retrieval-augmented generation adds a second place to fail. The answer can be wrong because the right passage was never retrieved, or because the model ignored it. Measure the two parts separately. The Ragas paper frames RAG evaluation along these lines: whether retrieval finds relevant, focused passages, whether the model uses them faithfully, and the quality of the generated answer. It proposes metrics that do not need human-written reference answers, which speeds up evaluation cycles.
A practical RAG checklist:
- Retrieval: for each test question, did the right document appear in the top results?
- Faithfulness: is every claim in the answer supported by the retrieved text?
- Answer quality: does it actually answer the question, completely and concisely?
- Abstention: does it say "I don't know" when the documents do not contain the answer?
To understand the moving parts, read our guide to the RAG pipeline, and see RAG vs fine-tuning for how the choice changes what you test.
How to Evaluate Agents and Tool Calls
Agents add actions to the mix. Evaluate the outcome (did the task get done correctly?) and the path (which tools were called, with what arguments, in what order?). Check that the system refuses actions it should not take. Our explainer on tool calling in LLMs covers why argument validation and permissions matter, and each of those is a testable behaviour.
Step 5: Run Evals Before Release and After Launch
Evaluation has two phases that feed each other.
Offline evals run on your golden dataset before release. Wire them into your development workflow so every prompt change, model swap or retrieval update triggers the same tests. Compare scores to the previous version. A drop in a category is a regression, just as in ordinary software.
Online evals watch real traffic after launch. Sample live conversations, run automated checks, collect user feedback such as thumbs up or down, and review failures. This is where AI observability comes in, and beginners can start with what AI observability is.
Close the loop: every real failure becomes a new test case. That is how a 40-case test set turns into a trustworthy safety net.
A Minimal Eval You Can Run Today
This small script scores an application against a golden set using simple code checks. Replace app with your own function that returns the model's answer. It was run with a stub function and returned the expected pass rate.
python
golden = [
{"q": "How many casual leave days per year?", "must_include": ["12"], "must_not": []},
{"q": "Can I carry forward sick leave?", "must_include": ["no"], "must_not": ["yes, unlimited"]},
]
def check(answer, case):
a = answer.lower()
has_all = all(s.lower() in a for s in case["must_include"])
has_none = not any(s.lower() in a for s in case["must_not"])
return has_all and has_none
def run(app, cases):
results = [check(app(c["q"]), c) for c in cases]
return sum(results) / len(results), results
It is crude, but it is repeatable, and repeatable is the point. Add LLM-as-a-judge and human review on top for what string checks cannot see.
A Worked Scenario: An HR Policy Assistant
This is a hypothetical example to show the method; the company and numbers are invented.
A mid-sized company in Pune launches an assistant that answers employee questions from its HR policy documents.
Define good. Correct policy answers, source cited, "contact HR" when the policy is silent, no disclosure of other employees' data.
Golden set. The team collects 45 real questions from the HR inbox, adds 10 edge cases (leave policies that changed mid-year, questions in Hinglish, a request for a colleague's salary) and 5 injection attempts hidden in uploaded documents.
Graders. Code checks verify key numbers and required phrases. An LLM judge scores faithfulness to the retrieved policy text, using a written rubric. HR staff review a sample of 20 judged answers to check the judge agrees with them.
Result. The first run shows retrieval problems on the changed-policy questions: the old document ranks first. The fix is to store effective dates and prefer the latest version. A second problem appears in Hinglish queries, where the assistant answers confidently without a source. The team adds an abstention rule and more test cases.
After launch. Thumbs-down responses are reviewed weekly. Each confirmed failure is added to the golden set, so the same mistake is caught next time.
Common Mistakes
- Evaluating only the model. The product is the whole pipeline.
- Testing on a handful of friendly prompts. Include hard and hostile cases.
- One overall score. Track categories so a regression cannot hide inside an average.
- Trusting the judge blindly. Calibrate against human grades.
- Tuning on the test set. Keep a held-out slice.
- Skipping online monitoring. Real users find cases you never imagined.
- Never updating the dataset. Evals that do not grow from failures go stale.
- Chasing public leaderboards. A model that tops a benchmark may still fail your task.
Why This Is a Career Skill
Teams building with LLMs need people who can design test sets, write rubrics, run evals and interpret failures. It sits within the growing field of LLM operations; see LLMOps vs MLOps and the breakdown of LLMOps engineer roles and responsibilities. Good prompts also depend on testing, as our guide to what prompt engineering is explains. We have not quoted salary figures here; check current listings before planning around a number.
TL;DR:
To evaluate an LLM application, define what "good" means for your use case, build a small golden dataset of real test cases, pick metrics that match the task, score outputs with a mix of code checks, human review and LLM-as-a-judge, and run the same tests before every release and after launch. Test the whole application, not only the model. Treat evals like unit tests that you keep growing from real failures.
How do you evaluate an LLM application?
Define what good means for your task, build a golden dataset of realistic test cases, choose metrics that match the task, score outputs with code checks, human review and LLM-as-a-judge, and run the same tests before each release and on live traffic afterwards.
What is the difference between model evaluation and application evaluation?
Model evaluation compares models on general benchmarks. Application evaluation tests your prompts, retrieval, tools and guardrails on your own tasks, which is what determines whether your product works.
What is LLM-as-a-judge and how reliable is it?
LLM-as-a-judge uses a strong model to grade another model's output against a rubric. Zheng et al. found GPT-4 reached over 80% agreement with human preferences, but the method has known biases, so calibrate it against human reviewers.
How many test cases do you need?
There is no fixed number. Start with 30 to 50 well-chosen cases that cover typical, edge and adversarial inputs, then grow the set from real failures. Coverage matters more than size.
How do you evaluate a RAG system?
Measure retrieval and generation separately: whether the right passages are retrieved, whether the answer is faithful to them, whether it answers the question well, and whether it abstains when the documents lack the answer.
What is the difference between offline and online evaluation?
Offline evaluation runs on a fixed golden dataset before release to catch regressions. Online evaluation monitors real traffic after launch through sampling, user feedback and automated checks, and feeds new failures back into the dataset.


Executive PG Certification in AI-Enabled VLSI Design
IIT Kharagpur
Architect the Silicon of Tomorrow: From Low-Power RTL to AI-Optimized GDSII.