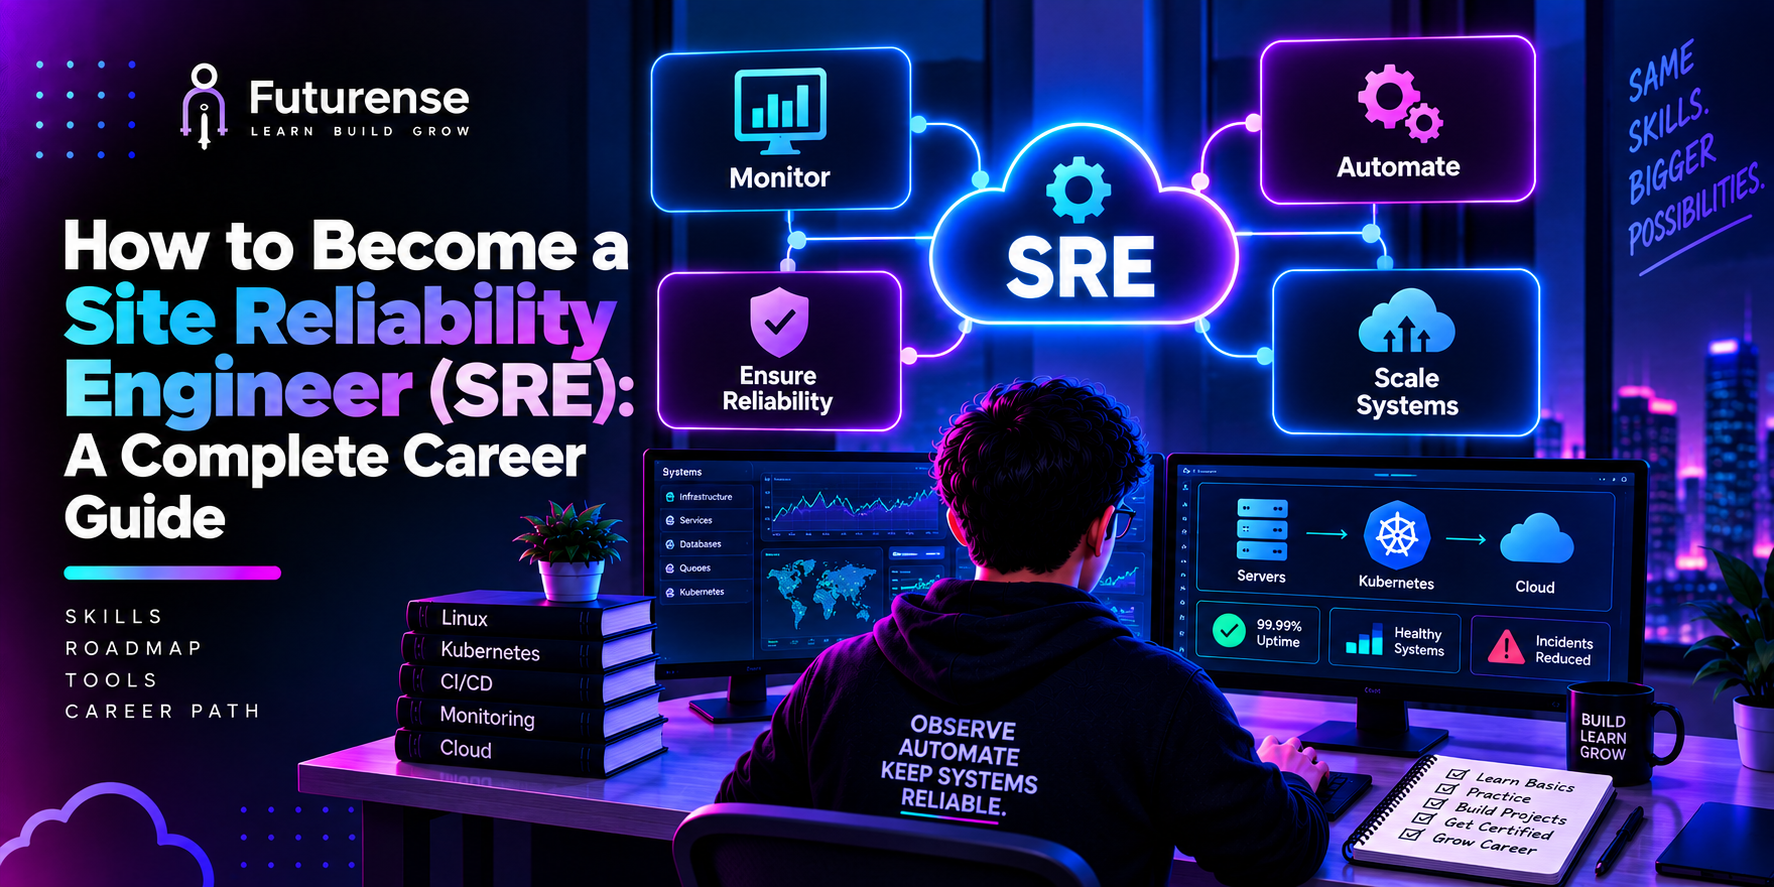


What a Site Reliability Engineer Actually Does
Site Reliability Engineering is the discipline of applying software engineering practices to operations problems treating reliability, scalability, and incident response as engineering challenges to be solved with code and automation, not just manual processes. The role was formalized at Google (the term and its founding practices come directly from Google's own SRE function) and has since become a standard function at any company running production systems at meaningful scale.
Day to day, an SRE writes automation to reduce manual operational work ("toil"), builds and maintains monitoring and alerting systems, participates in on-call rotations to respond to incidents, conducts blameless post-incident reviews, and works closely with software engineering teams to make new systems reliable and scalable before they ever reach production. The role sits deliberately at the intersection of development and operations which is also why it's so often confused with, or compared to, what is DevOps.
SRE vs DevOps: Why the Distinction Matters for Your Career Path
DevOps is a cultural philosophy and set of practices aimed at breaking down silos between development and operations teams. SRE is a specific, more prescriptive implementation of that philosophy, with concrete practices like error budgets and SLO-driven decision-making that give teams an objective way to balance reliability work against feature velocity.
In practice, many companies use the titles almost interchangeably, but understanding the distinction matters for career planning: SRE roles tend to have a more explicit engineering bar (strong coding ability is typically a hard requirement, not a nice-to-have) and a more structured, metrics-driven approach to reliability than a typical DevOps role. If you're deciding between the two paths, our guide on how to become a DevOps Engineer is a useful comparison point, and our broader DevOps Engineer vs Software Engineer piece covers the underlying skill-set overlap in more depth.
The Skills You Need to Become an SRE
Software Engineering Fundamentals
SRE is not an operations-only role most SRE job postings expect solid coding ability in at least one language commonly used for automation and tooling (Python and Go are the most common). You need to be able to write production-quality code, not just scripts, since SREs often build the internal tools and automation their teams rely on.
Systems and Networking Fundamentals
A working understanding of how operating systems, networking, and distributed systems actually behave under load and failure is foundational. This includes things like how DNS resolution works, how TCP connections behave under network partition, and how a distributed system degrades gracefully (or doesn't) when a dependency fails.
Infrastructure as Code and Automation
Modern SRE work is built on treating infrastructure the same way software engineers treat application code versioned, tested, and automated rather than manually configured. Tools like Terraform, Ansible, and configuration management systems are core to this, and familiarity with a broader toolchain is covered in our DevOps tools roundup, much of which overlaps directly with SRE tooling.
Kubernetes and Container Orchestration
Most modern production systems run on Kubernetes or a similar container orchestration platform, and SREs are typically expected to be comfortable operating, debugging, and scaling workloads on it not just deploying to it, but understanding its failure modes deeply enough to diagnose problems under pressure.
Observability and Monitoring
SREs live or die by their ability to see what's actually happening inside a production system: metrics, logs, traces, and the dashboards and alerting built on top of them. This isn't optional tooling knowledge it's the foundation of how an SRE actually does their job, from detecting incidents early to diagnosing root cause during one.
SLIs, SLOs, and Error Budgets
This is the conceptual core that distinguishes SRE from generic ops work: Service Level Indicators (what you measure), Service Level Objectives (the target for that measurement), and error budgets (how much unreliability is acceptable before reliability work takes priority over new features). Understanding how to define and use these isn't just theoretical it's the framework SREs use to make real prioritization decisions.
Incident Management and Communication
When something breaks in production, an SRE needs to lead or contribute to incident response calmly and effectively diagnosing root cause under pressure, communicating status to stakeholders, and running or participating in blameless post-incident reviews that turn failures into system improvements rather than blame exercises.
A Realistic Path: From Where You Are to SRE
If you're coming from software development: Your coding skills transfer directly. Focus on building systems and infrastructure knowledge get hands-on with Kubernetes, cloud infrastructure, and observability tooling, and look for opportunities to take on on-call responsibilities or infrastructure-adjacent projects within your current role to build relevant experience before making the jump.
If you're coming from DevOps or systems administration: Your operations and infrastructure knowledge transfers directly. Focus on strengthening your software engineering skills being able to write and maintain production-quality automation code, not just scripts, is often the gap between a DevOps background and a strong SRE candidacy.
If you're starting from a general computer science or engineering background: Build both halves deliberately. Start with strong programming fundamentals and a foundational understanding of cloud infrastructure since Cloud Engineer Roadmap-style infrastructure knowledge overlaps heavily with what SRE roles expect then layer in observability, Kubernetes, and incident management specifically.
Most engineers land their first dedicated SRE role after 2–5 years of relevant experience, though the exact timeline depends heavily on how much of the skill set you're building fresh versus transferring from an adjacent role.
What SREs Earn in India and Globally
Compensation for SREs in India varies significantly by experience level and company type, generally following a similar trajectory to other senior infrastructure and platform engineering roles. For a detailed breakdown by experience level and company tier, see our dedicated guide, Site Reliability Engineer Salary in India. Broadly, entry-to-mid-level SREs in India can expect roughly ₹8–20 LPA, with senior and staff-level SREs at larger tech companies and global-facing roles earning considerably more, often well above ₹35 LPA, and global remote SRE roles commanding significantly higher compensation still.
Where SRE Is Headed: AI-Driven Operations
Reliability engineering is increasingly incorporating AI-driven operations as production systems grow more complex automated anomaly detection, AI-assisted root cause analysis, and predictive alerting are becoming standard parts of a mature observability stack. Engineers building an SRE career today benefit from at least a working understanding of this direction; our guide on how to become an AIOps Engineer covers the specific skill set for teams applying AI directly to operations and reliability work, which is a natural adjacent specialization for an experienced SRE to grow into. Security is following a similar trajectory see our overview of DevSecOps for how security responsibilities are increasingly folding into the same reliability-and-operations skill set.
TL;DR: Becoming a Site Reliability Engineer means combining software engineering skills with systems and operations expertise to keep production systems reliable, scalable, and fast to recover from failure. The typical path runs through 2–5 years in software development, DevOps, or systems administration, then builds SRE-specific skills SLIs/SLOs and error budgets, infrastructure as code, Kubernetes, observability, and incident management before moving into a dedicated SRE role. In India, SRE salaries typically range from ₹8–35 LPA depending on experience, with senior and staff-level SREs earning significantly more at global tech companies.
What qualifications do you need to become a Site Reliability Engineer?
There's no single required degree or certification. Most SREs have a computer science or engineering background (or equivalent practical experience) and build role-specific skills coding, systems knowledge, Kubernetes, observability, and SLO-driven reliability practices through hands-on experience rather than a formal credentialing path.
How is a Site Reliability Engineer different from a DevOps Engineer?
DevOps is a broader cultural philosophy for breaking down silos between development and operations. SRE is a more prescriptive implementation of that philosophy with a stronger coding bar and concrete practices like SLOs and error budgets for making reliability decisions objectively.
How long does it take to become an SRE?
Most engineers land their first dedicated SRE role after roughly 2–5 years of relevant experience in software development, DevOps, or systems administration, depending on how much of the required skill set transfers directly versus needs to be built from scratch.
Do I need to know Kubernetes to become an SRE?
Kubernetes knowledge is expected at most companies today, since it's the dominant platform for running production workloads at scale, and SREs are typically responsible for operating and troubleshooting it under real production conditions, not just deploying to it.
Is SRE a good career path in India?
Yes SRE roles are in strong demand at both Indian tech companies and global companies hiring remotely, with compensation that scales meaningfully with experience and specialization, particularly for engineers who build strong skills in cloud infrastructure, Kubernetes, and observability.
What's the difference between SRE and traditional system administration?
Traditional system administration is largely manual and reactive. SRE treats the same operational responsibilities as an engineering problem automating manual work, applying software engineering rigor to infrastructure, and using objective metrics like SLOs to guide reliability decisions rather than ad hoc judgment calls.


Advanced Engineering Program in Applied AI, ML with Context Engineering
IITM Pravartak
Become the Context Engineer every AI & ML team needs to design scalable, business-driven workflows.